
Most people have used reverse image search without thinking much about what happens behind the scenes. Drop a photo into a search bar and back comes a list of visually similar pictures, sometimes the exact source of an image, sometimes products that look like it, sometimes nothing useful at all. The gap between those outcomes comes down to how well the underlying system was built.
Unlike a text search, there is no keyword to match. The system has to look at the actual visual content, shapes, colors, textures, and sometimes objects within the frame, and find other images that share those characteristics. This is one of the more mature image search techniques in everyday use today, quietly running behind features people rarely stop to name.
Understanding how it actually works helps explain both why it is useful and where it still falls short, especially for businesses considering building something similar into their own product.
The Basic Mechanics Behind It
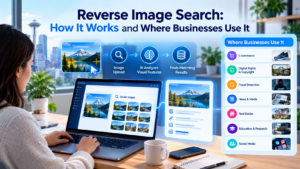
A reverse image search system typically converts an uploaded photo into a numerical representation, often called an embedding or feature vector, that captures its visual characteristics in a compressed form. This conversion is done by a neural network trained on large volumes of labeled images, learning to recognize patterns like edges, textures, and shapes well enough to represent a photo as a set of numbers rather than raw pixels.
Once an image is converted this way, finding similar images becomes a math problem: comparing the new photo’s numerical representation against a database of millions of pre-processed images and returning the closest matches. This is why the process feels instant even though it is comparing against an enormous index behind the scenes, the heavy computation happened ahead of time, not at the moment of the search.
Common Real-World Uses
Fact-checkers and journalists use reverse image search to verify whether a photo circulating online is genuinely recent or being recycled from an older, unrelated event. Shoppers use it to identify a product from a screenshot without knowing the brand name. Photographers and artists use it to check whether their work is being used without permission on other websites.
Businesses use it too, often for less visible purposes. Fraud teams check whether a product photo submitted by a seller was stolen from another listing. Trademark and brand protection teams scan the web for unauthorized use of logos or packaging. Real estate platforms use it to detect when a listing photo has been copied from a different property entirely.
Why Results Are Not Always Accurate
Lighting, angle, and cropping can all throw off a match, even when the underlying object is identical. A product photographed against a plain white background is far easier to match confidently than the same product photographed in a cluttered, real-world setting. Heavily edited or filtered images pose a similar problem, since visual features the model relies on can be altered enough to weaken the match.
There is also a scale trade-off. A larger, more comprehensive image index generally improves the odds of finding a true match, but it also increases the chance of surfacing coincidentally similar but unrelated images. Tuning that balance, comprehensiveness against precision, is one of the harder ongoing decisions in building this kind of system.
What It Takes to Build This Into a Product
Teams building this from scratch generally need three components: a model capable of generating reliable embeddings, a vector database or search index built to compare those embeddings efficiently at scale, and a pipeline to keep that index updated as new images are added or removed. Off-the-shelf vision models and managed vector database services have made this significantly more achievable than it was even a few years ago, when most of this had to be custom-built in-house.
The harder part is usually not the initial build but the ongoing maintenance, keeping the index fresh, monitoring for degraded match quality over time, and handling edge cases like near-duplicate images that should technically count as the same match but get scored separately due to minor pixel differences.
Where This Technology Is Headed
Reverse image search is increasingly being paired with generative models that can explain a match in plain language rather than just showing a grid of similar thumbnails. Instead of a wall of results, a system might say directly that a photo matches a specific product, describe why, and link to where it can be purchased or verified.
This blending of retrieval and explanation is part of a broader shift toward answer engines that treat an image the same way they treat a written question, expecting a direct, useful response rather than a raw list the user has to interpret themselves.
Getting Reliable Results From Reverse Image Lookup
Users who want more reliable results can help the system along in a few practical ways. Cropping a photo down to just the object of interest, rather than a wide scene with a lot of visual noise, tends to sharpen the match considerably. Using a higher-resolution source image also helps, since a low-quality or heavily compressed photo gives the model less detail to work with when generating its comparison.
For businesses running their own index, quality control on the input side matters just as much as the model itself. Regularly pruning duplicate or near-duplicate entries, standardizing image formats, and periodically re-processing the index as better embedding models become available all contribute meaningfully to match quality over time, even when nothing about the core search logic has changed. A neglected index is one of the more common, quietly self-inflicted reasons match quality declines over months without anyone on the team noticing until customers start complaining.
Documentation of the index’s own history is worth keeping too, which model version generated which embeddings, and when. Without that record, diagnosing why match quality shifted after an update becomes far harder, since a team ends up guessing whether the issue is the new content, the new model, or something else entirely.
Frequently Asked Questions
How does reverse image search actually work?
It converts a photo into a numerical representation of its visual features, then compares that representation against a large index of pre-processed images to find the closest visual matches.
Why do reverse image search results sometimes seem wrong?
Lighting, cropping, angle, and heavy editing can all change an image’s visual features enough to weaken or break a match, even when the underlying subject is identical.
What businesses use reverse image search outside of casual browsing?
Fraud and trust teams, brand protection teams, journalists verifying photos, and real estate platforms checking for duplicated listing images all rely on it regularly.
What does it take to build reverse image search into a product?
A model that generates reliable image embeddings, a vector database to compare those embeddings at scale, and an ongoing pipeline to keep the image index updated.
Is reverse image search the same as general visual search?
It is closely related. Reverse image search typically focuses on finding the same or visually similar images, while broader visual search often adds product matching, categorization, and recommendation on top.
How can a user get more accurate reverse image search results?
Cropping the photo down to just the object of interest and using a higher-resolution source image both tend to noticeably improve match accuracy.